
Where Data Tells the Story
© Voronoi 2026. All rights reserved.

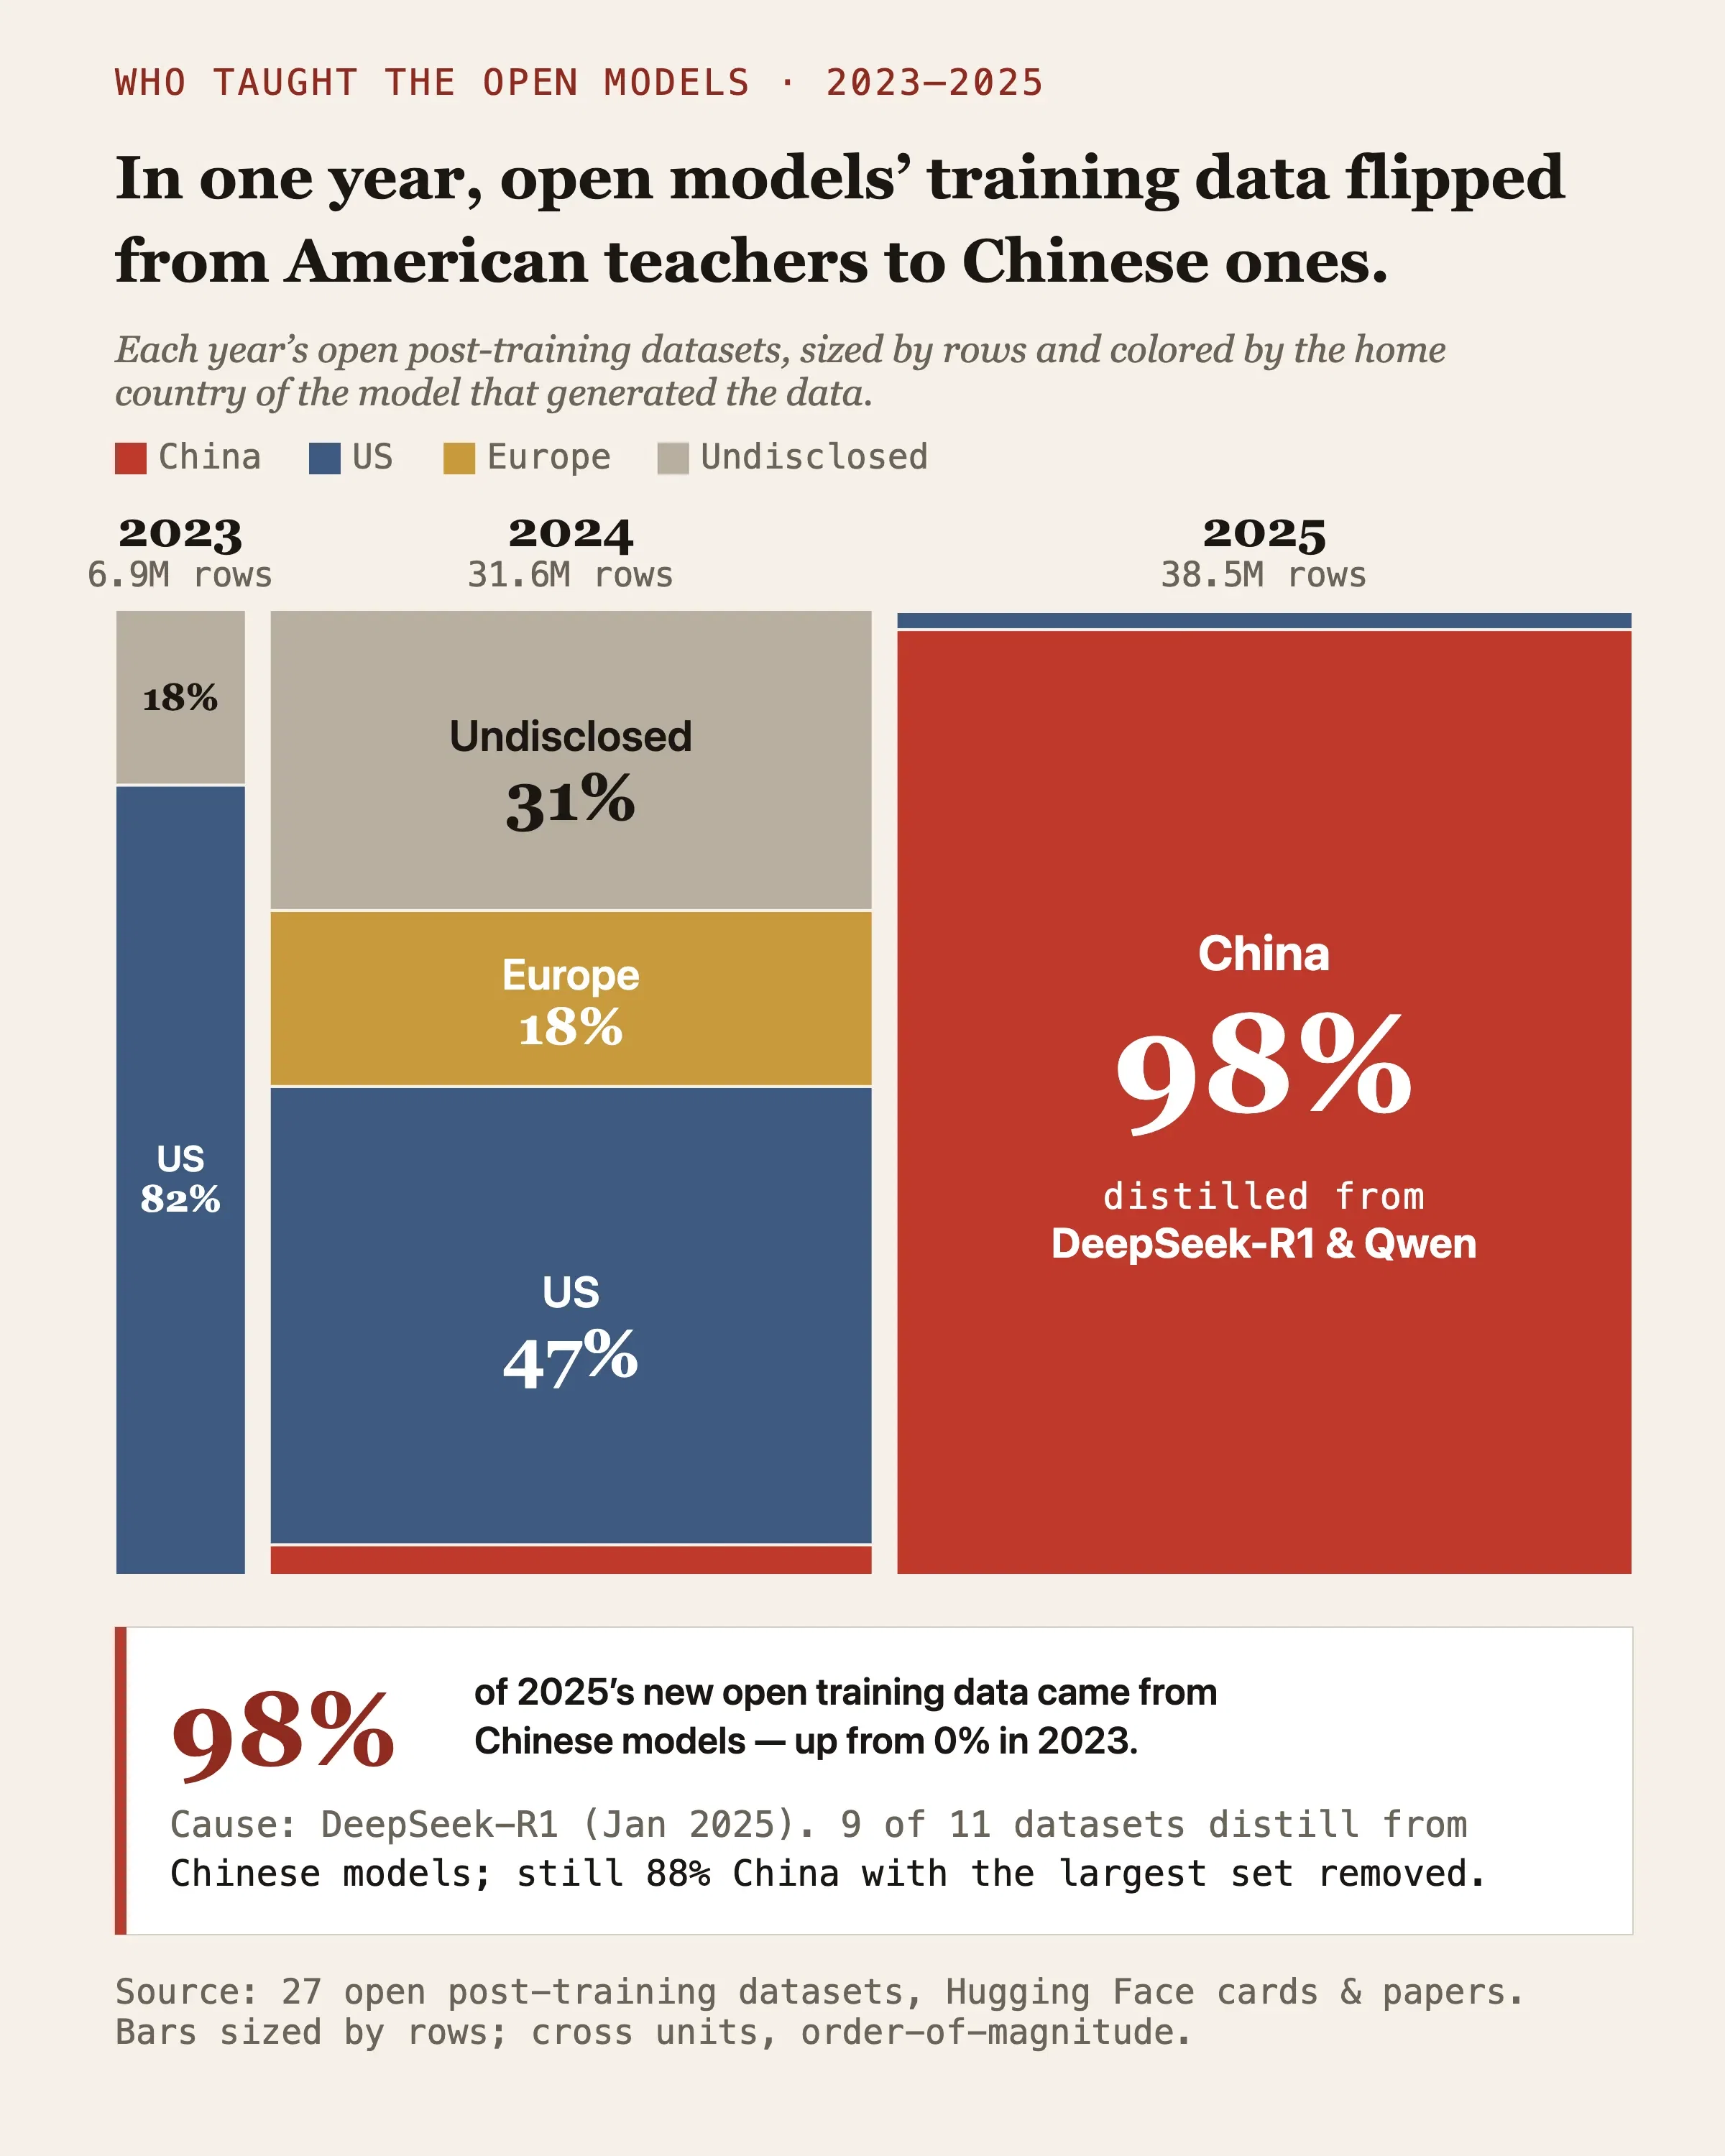
Many open language models are trained partly on synthetic data: text generated by a stronger model, a practice called distillation. Which models generated that text?
We looked at 27 widely used open post-training datasets (the data used to fine-tune a model after its initial training) released from 2023 to 2025. In 2023, American models generated 82% of the data, measured in rows, mostly OpenAI's GPT family. In 2024 the teachers were still Western, split between US and European models.
In 2025, Chinese models generated 98% of the new open training data, led by DeepSeek and Alibaba's Qwen.
One model drove the change. DeepSeek-R1, released in January 2025, became the default teacher for that year's open reasoning datasets. Of the 11 datasets in the 2025 sample, 9 distill from Chinese models. Without the largest one, NVIDIA's Nemotron, the Chinese share is still 88%.
Bars are sized by dataset row counts. Rows mix units (instructions, completions, reasoning traces), so treat the bars as order-of-magnitude estimates. Datasets that don't name their teacher model are marked Undisclosed, and one or two large releases make up most of each year's total.
The chart measures where training data was generated. Which country publishes or downloads the most models is a separate question.